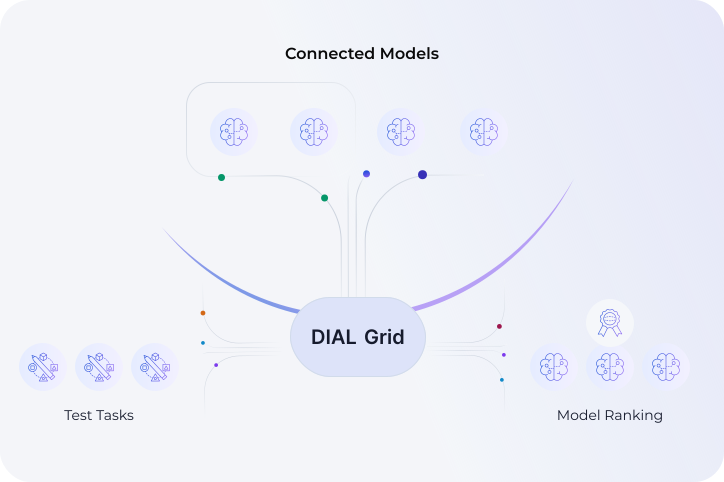
DIAL Grid
A model benchmarking tool inside DIAL Admin Panel that helps you select the right AI model for your task based on test runs with cost, speed and quality for each one.

Test on Your Own Tasks
Upload the tasks you actually need a model to do, along with the answer you expect for each one. Grid keeps them as a test set you can edit and extend.
Public leaderboards tell you how models rank on somebody else's problems. Grid tells you how they perform on yours.

One Model per Step, Not One for Everything
Most use cases are several LLM tasks in a row, not one. Split them into atomic test cases and Grid shows how each model handles each step.
So you can choose a different model for every step, and end up with a better combination than any single model would give you. You might use a cheap, fast model for classification and a stronger one where the reasoning matters.

Every Model You Have Connected, and Every Setting
Every model connected to your DIAL Gateway is available to test. As you connect new ones, they appear as candidates.
Settings count as candidates too. The same model at two reasoning levels can be tested as two entries, because for plenty of tasks the cheaper setting is good enough.

Cost, Speed and Quality Side by Side
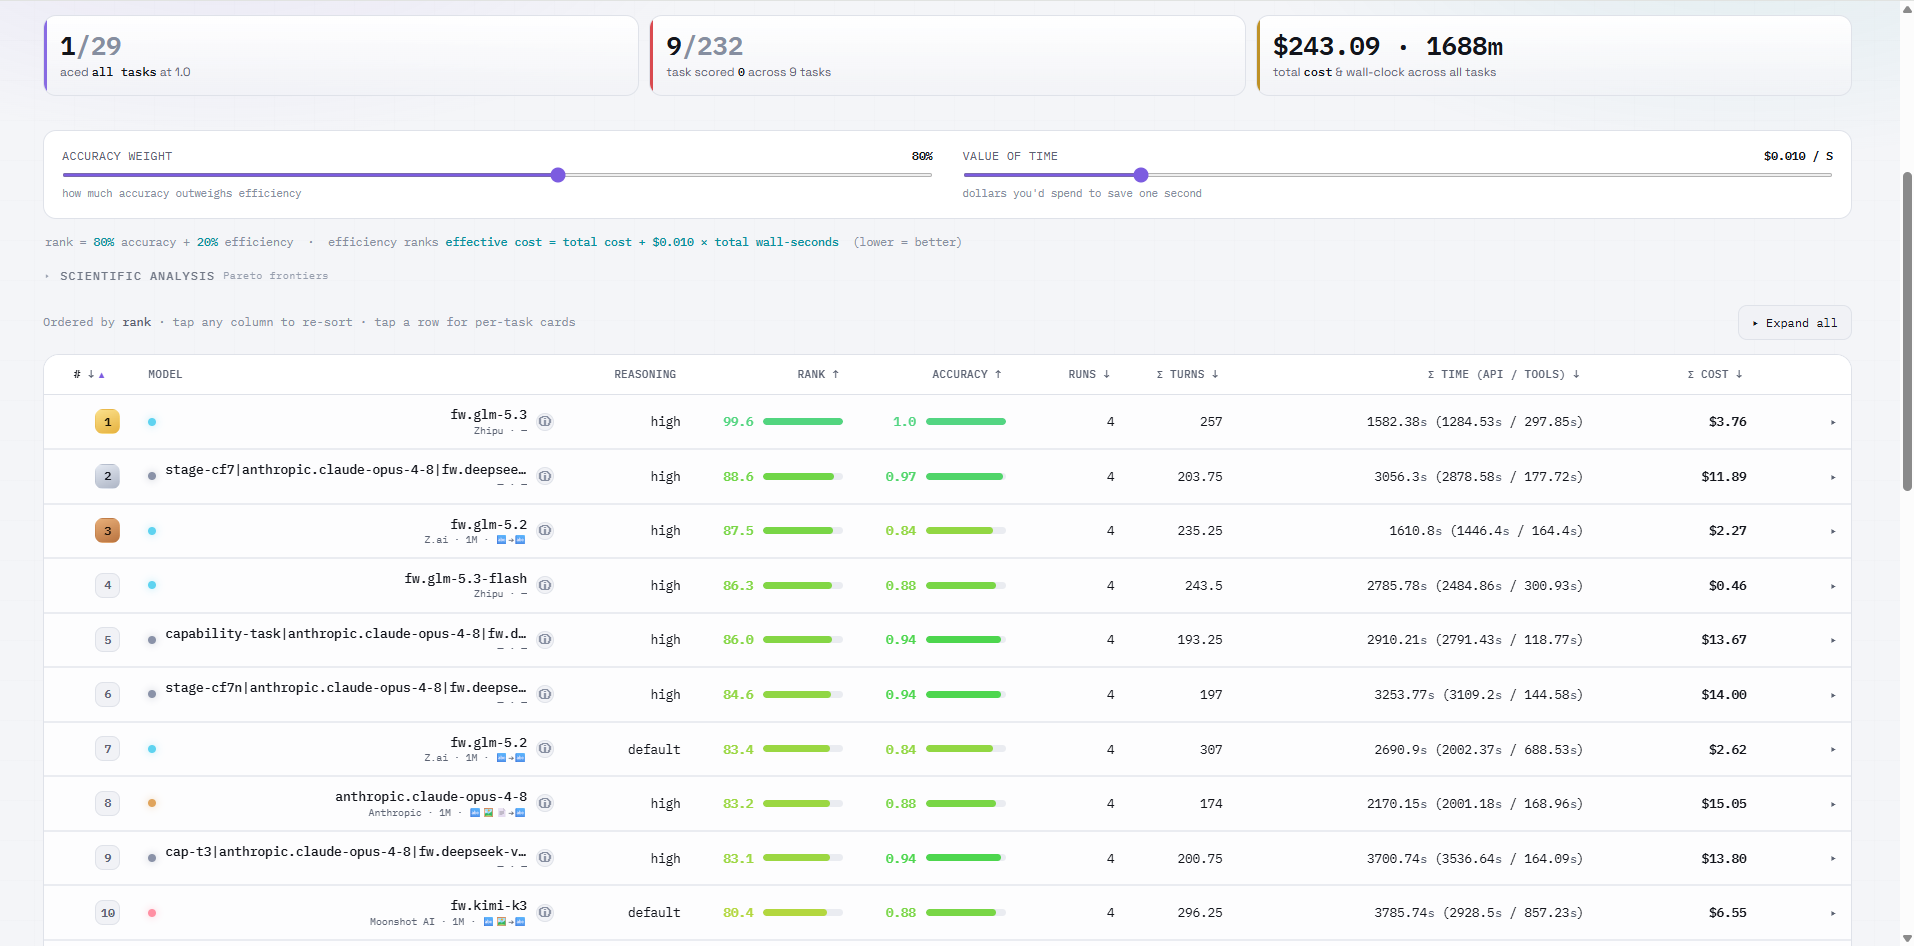
Set how many times each task should run and Grid averages the results. You get duration, token counts and cost per model, plus a similarity score against the answer you provided.
Everything lands in one table you can sort and filter. No recommendation and no black box, just the numbers next to each other.

Re-run It When the Models Change
New models ship constantly, and the best choice for a task changes with them. Your test set stays where it is, so running it against a new arrival takes minutes.
The models you already chose can drift too. Providers update them, and a task that scored well six months ago may score differently now. Running the same set again is how you find out.
As the use case grows, add tasks to the set. Over time it becomes a record of what you tested and why you chose what you chose.

Grid or Eval?
Grid tests models. Eval tests your application.
Grid works on atomic tasks and answers which model to use where. Eval works on the finished use case. It answers whether the output is good enough, and whether a change made it better or worse.
Most teams end up using both. Grid to choose, Eval to keep it honest once it ships.
Grid Run Result Dashboard